How to Fix OpenAI Rate Limit Error 429 Using Exponential Backoff
Quick Answer
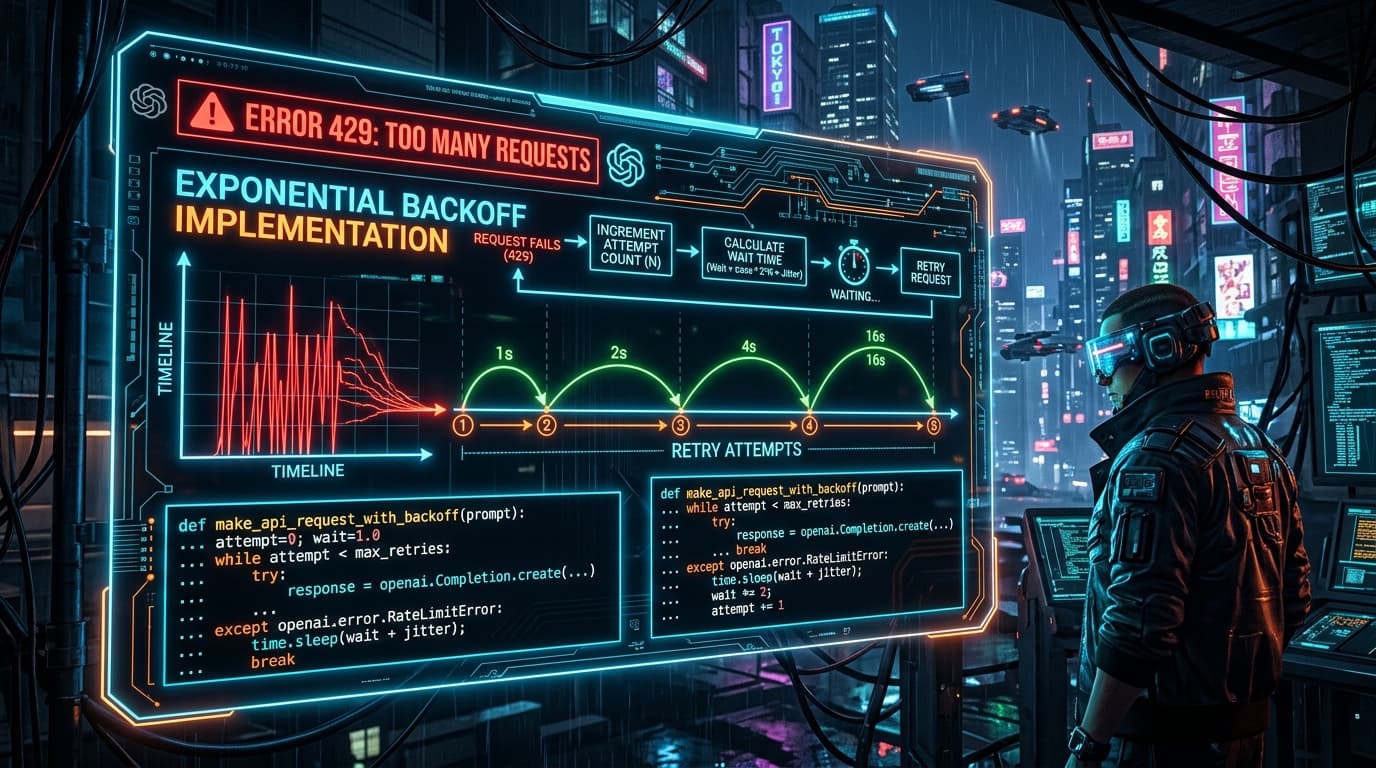
OpenAI Error 429 indicates you have hit your rate limit (Too Many Requests). The most reliable way to fix and prevent this error is by implementing an exponential backoff retry strategy in your API calls, which progressively increases the wait time between failed requests.
- Error 429 means you are sending too many requests or tokens too fast for your tier.
- Exponential backoff involves waiting progressively longer periods before retrying failed requests.
- Using official libraries or custom wrapper functions ensures your application recovers gracefully without crashing.
How to Fix OpenAI Rate Limit Error 429 Using Exponential Backoff
Building production-grade applications on top of Large Language Models (LLMs) requires resilient system design. If you are scaling an application powered by OpenAI's API, encountering OpenAI error 429 too many requests is an inevitable rite of passage. Whether you are running batch-processing pipelines, real-time chatbots, or automated content generators, hitting your tier's throughput ceiling will eventually cause your application to throw a wobbler unless you handle it proactively.
In this comprehensive technical guide, we will break down why this error occurs, explore the mathematical and architectural foundations of the exponential backoff algorithm api, and provide a bulletproof openai api retry strategy code snippet written in Python. By the end of this article, your integration will be fully equipped to handle high-concurrency environments gracefully.
Understanding OpenAI Error 429 and Rate Limits
When your application receives an HTTP 429 Too Many Requests response from the OpenAI API, it means that you have exceeded the usage thresholds assigned to your account tier. OpenAI enforces these limits to maintain infrastructure stability, prevent denial-of-service vectors, and ensure fair resource allocation across millions of developers globally.
What Triggers Rate Limits?
OpenAI measures consumption along several distinct dimensions depending on the specific model and endpoint you are invoking:
- RPM (Requests Per Minute): The total number of calls made to the API endpoint within a sixty-second window.
- RPD (Requests Per Day): A daily ceiling on overall request volume, typically enforced on lower usage tiers.
- TPM (Tokens Per Minute): The combined sum of prompt tokens and generated completion tokens processed within a minute. This is frequently the hidden bottleneck for developers working with large context windows.
Usage Tiers and Limits
OpenAI categorizes accounts into multiple tiers (Tier 1 through Tier 5). As your cumulative spend and account age increase, OpenAI automatically upgrades your tier, raising your RPM and TPM caps. However, even on Tier 5, sudden spikes in concurrent user traffic can quickly saturate your token capacity.
Developer Note: Relying solely on manual tier upgrades is an anti-pattern. Even at the highest tiers, network congestion, sudden traffic spikes, or recursive background tasks can trigger a 429 error. Your application code must assume rate limits will happen and implement defensive retry logic.
What is Exponential Backoff and Why Use It?
When an API returns a 429 error, the simplest naive approach is to catch the exception and immediately retry the request. This is known as a linear retry or immediate retry. In a high-concurrency environment, immediate retries are catastrophic. If 50 parallel threads all fail simultaneously and instantly retry, they bombard the API with an even larger wave of traffic, compounding the congestion and ensuring that subsequent requests fail as well. This phenomenon is known as a retry storm.
The Mechanics of Exponential Backoff
To prevent retry storms, engineers use exponential backoff. Exponential backoff is a standard error-handling strategy in distributed systems where an application periodically retries a failed request with progressively longer wait times between attempts.
The algorithm typically follows this mathematical progression:
$$\text{Delay} = \text{Initial Delay} \times \text{Base}^{\text{Attempt Number}}$$
Typically, the base is set to 2 (binary exponential backoff). For example:
- Attempt 1 (Failure): Wait 1 second
- Attempt 2 (Failure): Wait 2 seconds
- Attempt 3 (Failure): Wait 4 seconds
- Attempt 4 (Failure): Wait 8 seconds
- Attempt 5 (Failure): Raise exception / Give up
Adding Jitter
In high-scale distributed systems, multiple clients might hit a rate limit at the exact same millisecond. If they all use the exact same exponential backoff formula, they will all retry at the exact same synchronized intervals, creating secondary traffic spikes.
To neutralize this, production systems introduce jitter—a randomizing variable added to the sleep duration. Jitter disperses retry requests across a time window, drastically reducing collision rates and ensuring smoother traffic recovery.
Implementing Exponential Backoff in Python
To handle openai rate limits python developers can write custom wrapper functions or leverage official SDK error classes. Below is a production-ready implementation utilizing the modern OpenAI Python SDK (openai>=1.0.0), featuring exponential backoff and explicit handling of the RateLimitError exception.
import time
import random
import openai
from openai import RateLimitError

def call_openai_with_backoff(prompt, max_retries=5, initial_delay=1):
    """
    Sends a prompt to OpenAI's Chat Completions API with exponential backoff
    and randomized jitter to safely handle RateLimitError (429).
    """
    delay = initial_delay

    for attempt in range(max_retries):
        try:
            response = openai.chat.completions.create(
                model="gpt-4o",
                messages=[{"role": "user", "content": prompt}]

            )
            return response.choices[0].message.content

        except RateLimitError as e:
            if attempt == max_retries - 1:
                print(f"[Error] Max retries ({max_retries}) reached. Failing request.")
                raise e

            # Apply exponential backoff with a small amount of random jitter (0-1 sec)
            sleep_time = delay + random.uniform(0, 1)
            print(f"[Warning] Rate limit hit (429). Retrying in {sleep_time:.2f} seconds... (Attempt {attempt + 1}/{max_retries})")

            time.sleep(sleep_time)
            delay *= 2  # Double the delay for the next iteration

        except openai.APIConnectionError as e:
            # Network-level errors can also benefit from backoff
            if attempt == max_retries - 1:
                raise e
            time.sleep(delay)
            delay *= 2

# Example usage:
if __name__ == "__main__":
    try:
        result = call_openai_with_backoff("Explain quantum computing in one sentence.")
        print("\nAI Response:\n", result)
    except Exception as err:
        print(f"Execution failed: {err}")
Breaking Down the Code
- Exception Catching: We explicitly catch
openai.RateLimitError, ensuring that genuine application errors (such as invalid API keys or malformed JSON payloads) are not accidentally swallowed and retried infinitely. - Attempt Counter: The
forloop tracks attempts againstmax_retries, throwing an exception if the API remains unresponsive after the threshold is breached. - Delay Multiplier: Inside the
exceptblock,delay *= 2doubles the waiting period with each subsequent failure. - Jitter Integration:
random.uniform(0, 1)adds randomized dispersion to prevent synchronized retries across multiple workers.
Best Practices to Avoid OpenAI Rate Limits
Implementing retry logic is vital for error recovery, but architectural optimization is what stops rate limits from happening in the first place. Follow these best practices to maximize your API efficiency:
1. Optimize Token Consumption
Because TPM (Tokens Per Minute) is often the tightest restriction, reducing your payload size yields immediate throughput gains:
- Trim System Prompts: Remove conversational filler and redundant instructions from your system prompt.
- Manage Context Windows: Avoid passing the entire historical transcript of a conversation if only the last few turns are relevant. Implement smart summarization or sliding-window history management.
- Choose the Right Model: Use lighter models like
gpt-4o-minifor routine classification, data extraction, or formatting tasks, reserving heavy models likegpt-4ostrictly for complex reasoning.
2. Implement Client-Side Rate Limiting (Token Buckets)
Before firing requests off to the network, your application can proactively throttle itself using client-side rate limiters. Libraries like Python's ratelimit package or custom asynchronous token bucket queues allow you to pace outgoing requests so they never breach your tier limits in the first place.
3. Asynchronous Batch Processing
If you need to process thousands of records (e.g., summarizing user reviews or embedding documents), do not execute synchronous loops. Instead:
- Utilize OpenAI’s Batch API, which offers a 50% discount and operates on separate, highly generous asynchronous rate limits.
- If real-time processing is mandatory, use Python's
asynciopaired withasyncio.sleepto orchestrate concurrency safely.
Troubleshooting Advanced API Concurrency Issues
If you have implemented exponential backoff and are still experiencing persistent 429 errors, consider these advanced debugging vectors:
- Distributed Workers: Are you running multiple independent worker containers (e.g., Celery workers, Kubernetes pods, AWS Lambda functions) that share a single OpenAI account? If so, each worker is blind to the requests made by other workers. Total aggregate consumption across all containers must be factored into your client-side concurrency limits.
- Incorrect Organization Header: Ensure your API keys are scoped properly and that you are not inadvertently running multiple independent client applications under a restrictive default organization ID.
- Monitoring Usage Dashboards: Regularly inspect your usage metrics on the OpenAI developer dashboard. Analyze the granular spikes to determine whether your rate limits are being breached due to sudden traffic surges or steady-state overload.
By combining robust exponential backoff code with intelligent prompt architecture and proactive token management, you can build reliable, enterprise-grade AI systems that shrug off network congestion and maintain flawless uptime.
Copy Prompt Box
Last verified on Nov 5, 2026 by the PromptGrid AI Editorial Team.