Fixing the LangChain Context Length Error: A Production Guide to Smart Chunking
Quick Answer
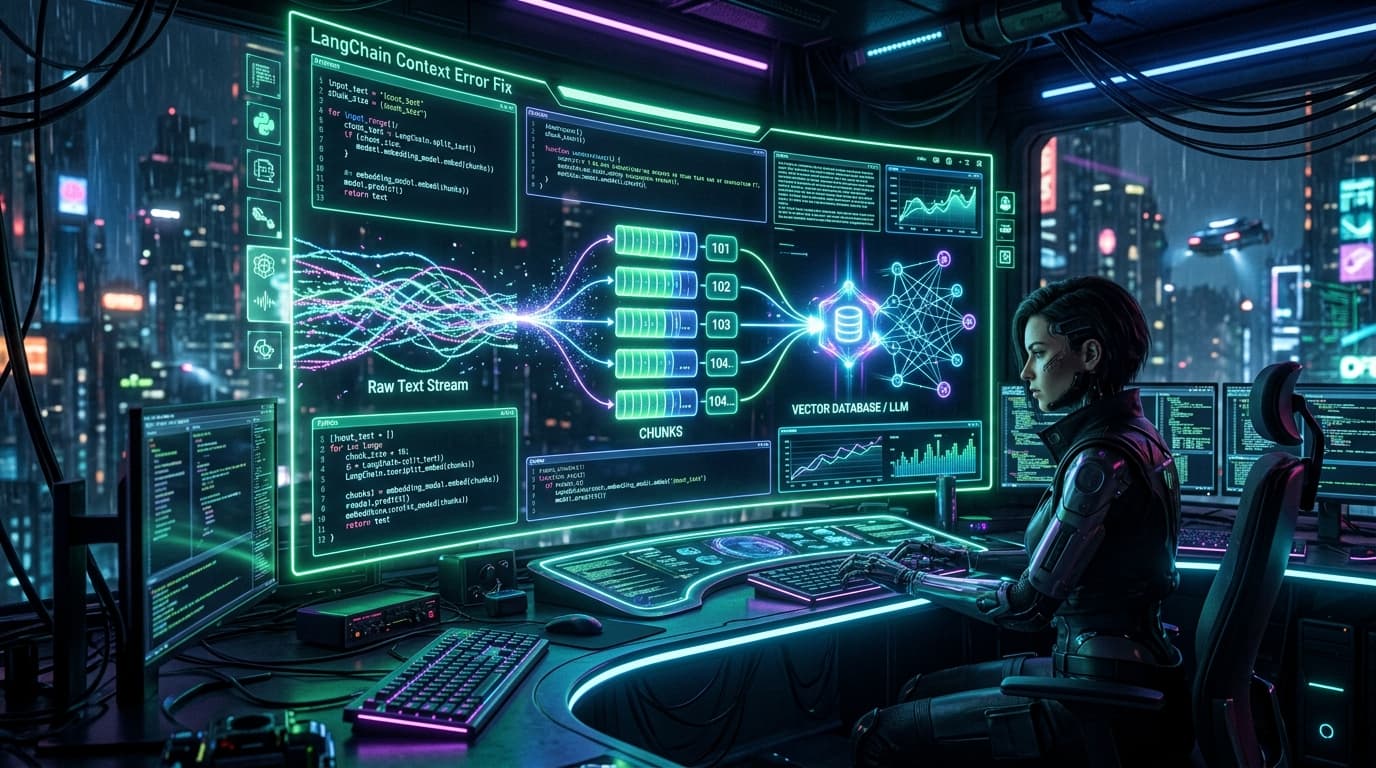
The 'context length exceeded' error in LangChain occurs when the input text exceeds the maximum token limit of the underlying LLM. The standard fix is to implement text chunking using LangChain's built-in text splitters, such as RecursiveCharacterTextSplitter, to break large documents into smaller, manageable pieces before passing them to the model.
- Identify the token limit of your specific LLM model (e.g., GPT-4, Claude).
- Use RecursiveCharacterTextSplitter to split documents logically by paragraphs or sentences.
- Configure appropriate 'chunk_size' and 'chunk_overlap' parameters to maintain semantic context.
It is 2:14 AM. PagerDuty is screaming. Your production pipeline just hard-crashed on a routine PDF ingest, and the traceback throws the dreaded error:
RateLimitError: Error code: 400 - {'error': {'message': 'This model\'s maximum context length is 8192 tokens. However, your messages resulted in 14,203 tokens.'}}
Sound familiar?
If you are building Retrieval-Augmented Generation (RAG) systems or feeding raw enterprise documents into LangChain, you are going to hit the context window ceiling. It is not a matter of if, but when. Large language models have hard boundaries. No matter how much venture capital you raised, GPT-4, Claude 3.5 Sonnet, and Llama 3 simply cannot ingest an entire corporate filing, a 300-page technical manual, or a messy database dump in a single API call.
Let's roll up our sleeves and fix this properly.
Understanding the LangChain Context Length Error
Why does this error happen in the first place?
At its core, an LLM doesn't read words. It reads tokens. A token is roughly three-quarters of an English word, though punctuation, code syntax, and non-Latin characters can aggressively skew that ratio. When you pass a massive document directly into a LangChain chain or vector store without pre-processing, you are blindly hurling a mountain of text at an endpoint with a fixed capacity.
Here is the mental model: Imagine trying to shove a king-sized mattress through a cat flap. That is your 15,000-token PDF hitting an 8,192-token context window.
[ Massive Raw Document (~15k tokens) ]
            │
            ▼
   💥 CRASH: Context Length Exceeded
            │
            ▼
[ LLM API Endpoint (8k Limit) ]
When LangChain constructs the prompt, it doesn't just include your raw text. It wraps your payload inside system prompts, few-shot examples, chat history, and formatting instructions. That overhead eats into your token budget before your actual data even gets evaluated.
Don't just increase the model context size blindly. Sure, newer models boast 128k or even 1M token windows. But shoveling entire codebases into an LLM context window is an expensive, high-latency anti-pattern. Costs explode, attention degrades in the middle of long contexts (the infamous 'lost in the middle' phenomenon), and inference crawls to a halt.
Why Chunking is the Best Solution for LLM Token Limits
Chunking is the architectural equivalent of slicing a loaf of bread. Instead of choking your model with an entire monolithic document, you break the text down into bite-sized, semantically coherent segments.
| Approach | Pros | Cons | Production Verdict |
|---|---|---|---|
| Full Document Ingestion | Zero data loss, preserves global context | Hits token limits, high cost, poor retrieval precision | Never use for docs > 2k tokens |
| Naive Character Splitting | Extremely fast, simple to implement | Cuts words/sentences in half, destroys semantic meaning | Avoid unless prototyping |
| Recursive Chunking | Respects natural text boundaries, keeps context intact | Requires tuning parameters | Industry Standard |
When you chunk correctly, you achieve two massive wins:
- You stay safely within token limits, avoiding API rejections.
- You drastically improve retrieval relevance. Vector similarity searches work dramatically better when matching against tight, highly specific paragraphs rather than sprawling multi-page sections.
Step-by-Step Guide to Implementing Text Splitters in LangChain
Stop writing custom regex scripts to split your strings by periods and spaces. LangChain provides robust, production-ready utilities out of the box.
The gold standard for general-purpose document ingestion is the RecursiveCharacterTextSplitter. Unlike basic splitters that chop text ruthlessly at arbitrary character counts, the recursive splitter tries a tiered list of separators—typically paragraphs (\n\n), lines (\n), spaces ( ), and characters ("")—until it finds a split that keeps related text together.
Here is how you wire it up in production:
from langchain.text_splitter import RecursiveCharacterTextSplitter

# Initialize your massive document text
raw_document = "... your 50,000-word enterprise document ..."

text_splitter = RecursiveCharacterTextSplitter(
    chunk_size=1000,
    chunk_overlap=200,
    length_function=len,
    add_start_index=True,
)

chunks = text_splitter.create_documents([raw_document])

print(f"Generated {len(chunks)} chunks without exceeding context limits.")
print(f"Sample chunk preview: {chunks[0].page_content[:200]}...")
If you inspect the output chunks, you will notice something wonderful: each chunk retains metadata tracking its original character index (add_start_index=True). This makes debugging retrieval errors a breeze when you need to trace a vector back to its source.
Best Practices for Setting Chunk Size and Chunk Overlap
Configuring chunk_size and chunk_overlap is where most developers guess blindly and wonder why their RAG pipeline hallucinates.
Here is the reality: There is no universal magic number.
- Chunk Size (
1000to1500characters): This is a safe baseline for English text when using standard embedding models liketext-embedding-3-small. It provides enough linguistic context for the embedding model to understand the semantic meaning without diluting the signal. - Chunk Overlap (
150to200characters): Why overlap? Imagine a critical sentence explaining a system configuration is split right down the middle across Chunk A and Chunk B. Without overlap, both chunks lose the complete thought. Overlap ensures that boundary-crossing concepts are captured in both adjacent chunks.
Pro-Tip from the Trenches: Always align your chunk size with your embedding model's optimal input size, and test your retrieval accuracy using evaluation frameworks like Ragas or TruLens before shipping to production.
Watch out for hidden gotchas:
- Code files: Standard text splitters will brutally break Python functions across chunks by splitting on newlines. If you are ingesting source code, use
Language.PYTHONwithRecursiveCharacterTextSplitter.from_language()to respect class and function definitions. - Tables and Markdown: Heavy tabular data stored in markdown will look like gibberish to standard recursive splitters. Pre-process tables into structured JSON strings or use specialized parsers before chunking.
Verifying Your Fix and Testing Document Retrieval
Once you have implemented your splitter, do not just assume it works. Write an integration test to verify that every single generated chunk fits comfortably within your target model's token constraints.
import tiktoken

enc = tiktoken.encoding_for_model("gpt-4")

for i, chunk in enumerate(chunks):
    token_count = len(enc.encode(chunk.page_content))
    if token_count > 8192:
        raise ValueError(f"Chunk {i} exceeds token limit with {token_count} tokens!")

print("All chunks verified successfully against token limits.")
Run this validation check in your CI/CD pipeline before deploying document loaders. Catching a rogue multi-thousand-token payload in a test suite beats waking up at 2 AM every single time.
Copy Prompt Box
Last verified on Nov 5, 2026 by the PromptGrid AI Editorial Team.